Watch the final project demonstration
The actual demonstration plays here on this page.
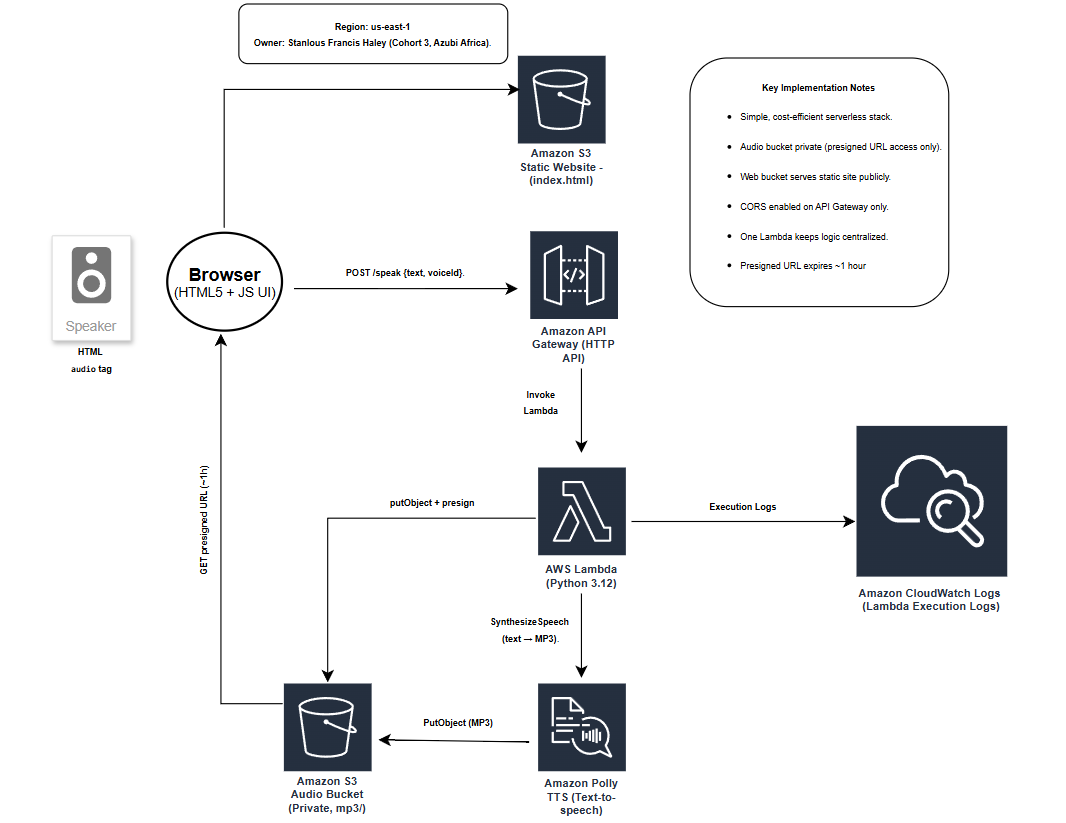
Architecture and project outcome
Actual diagrams and application screenshots from the project repository.
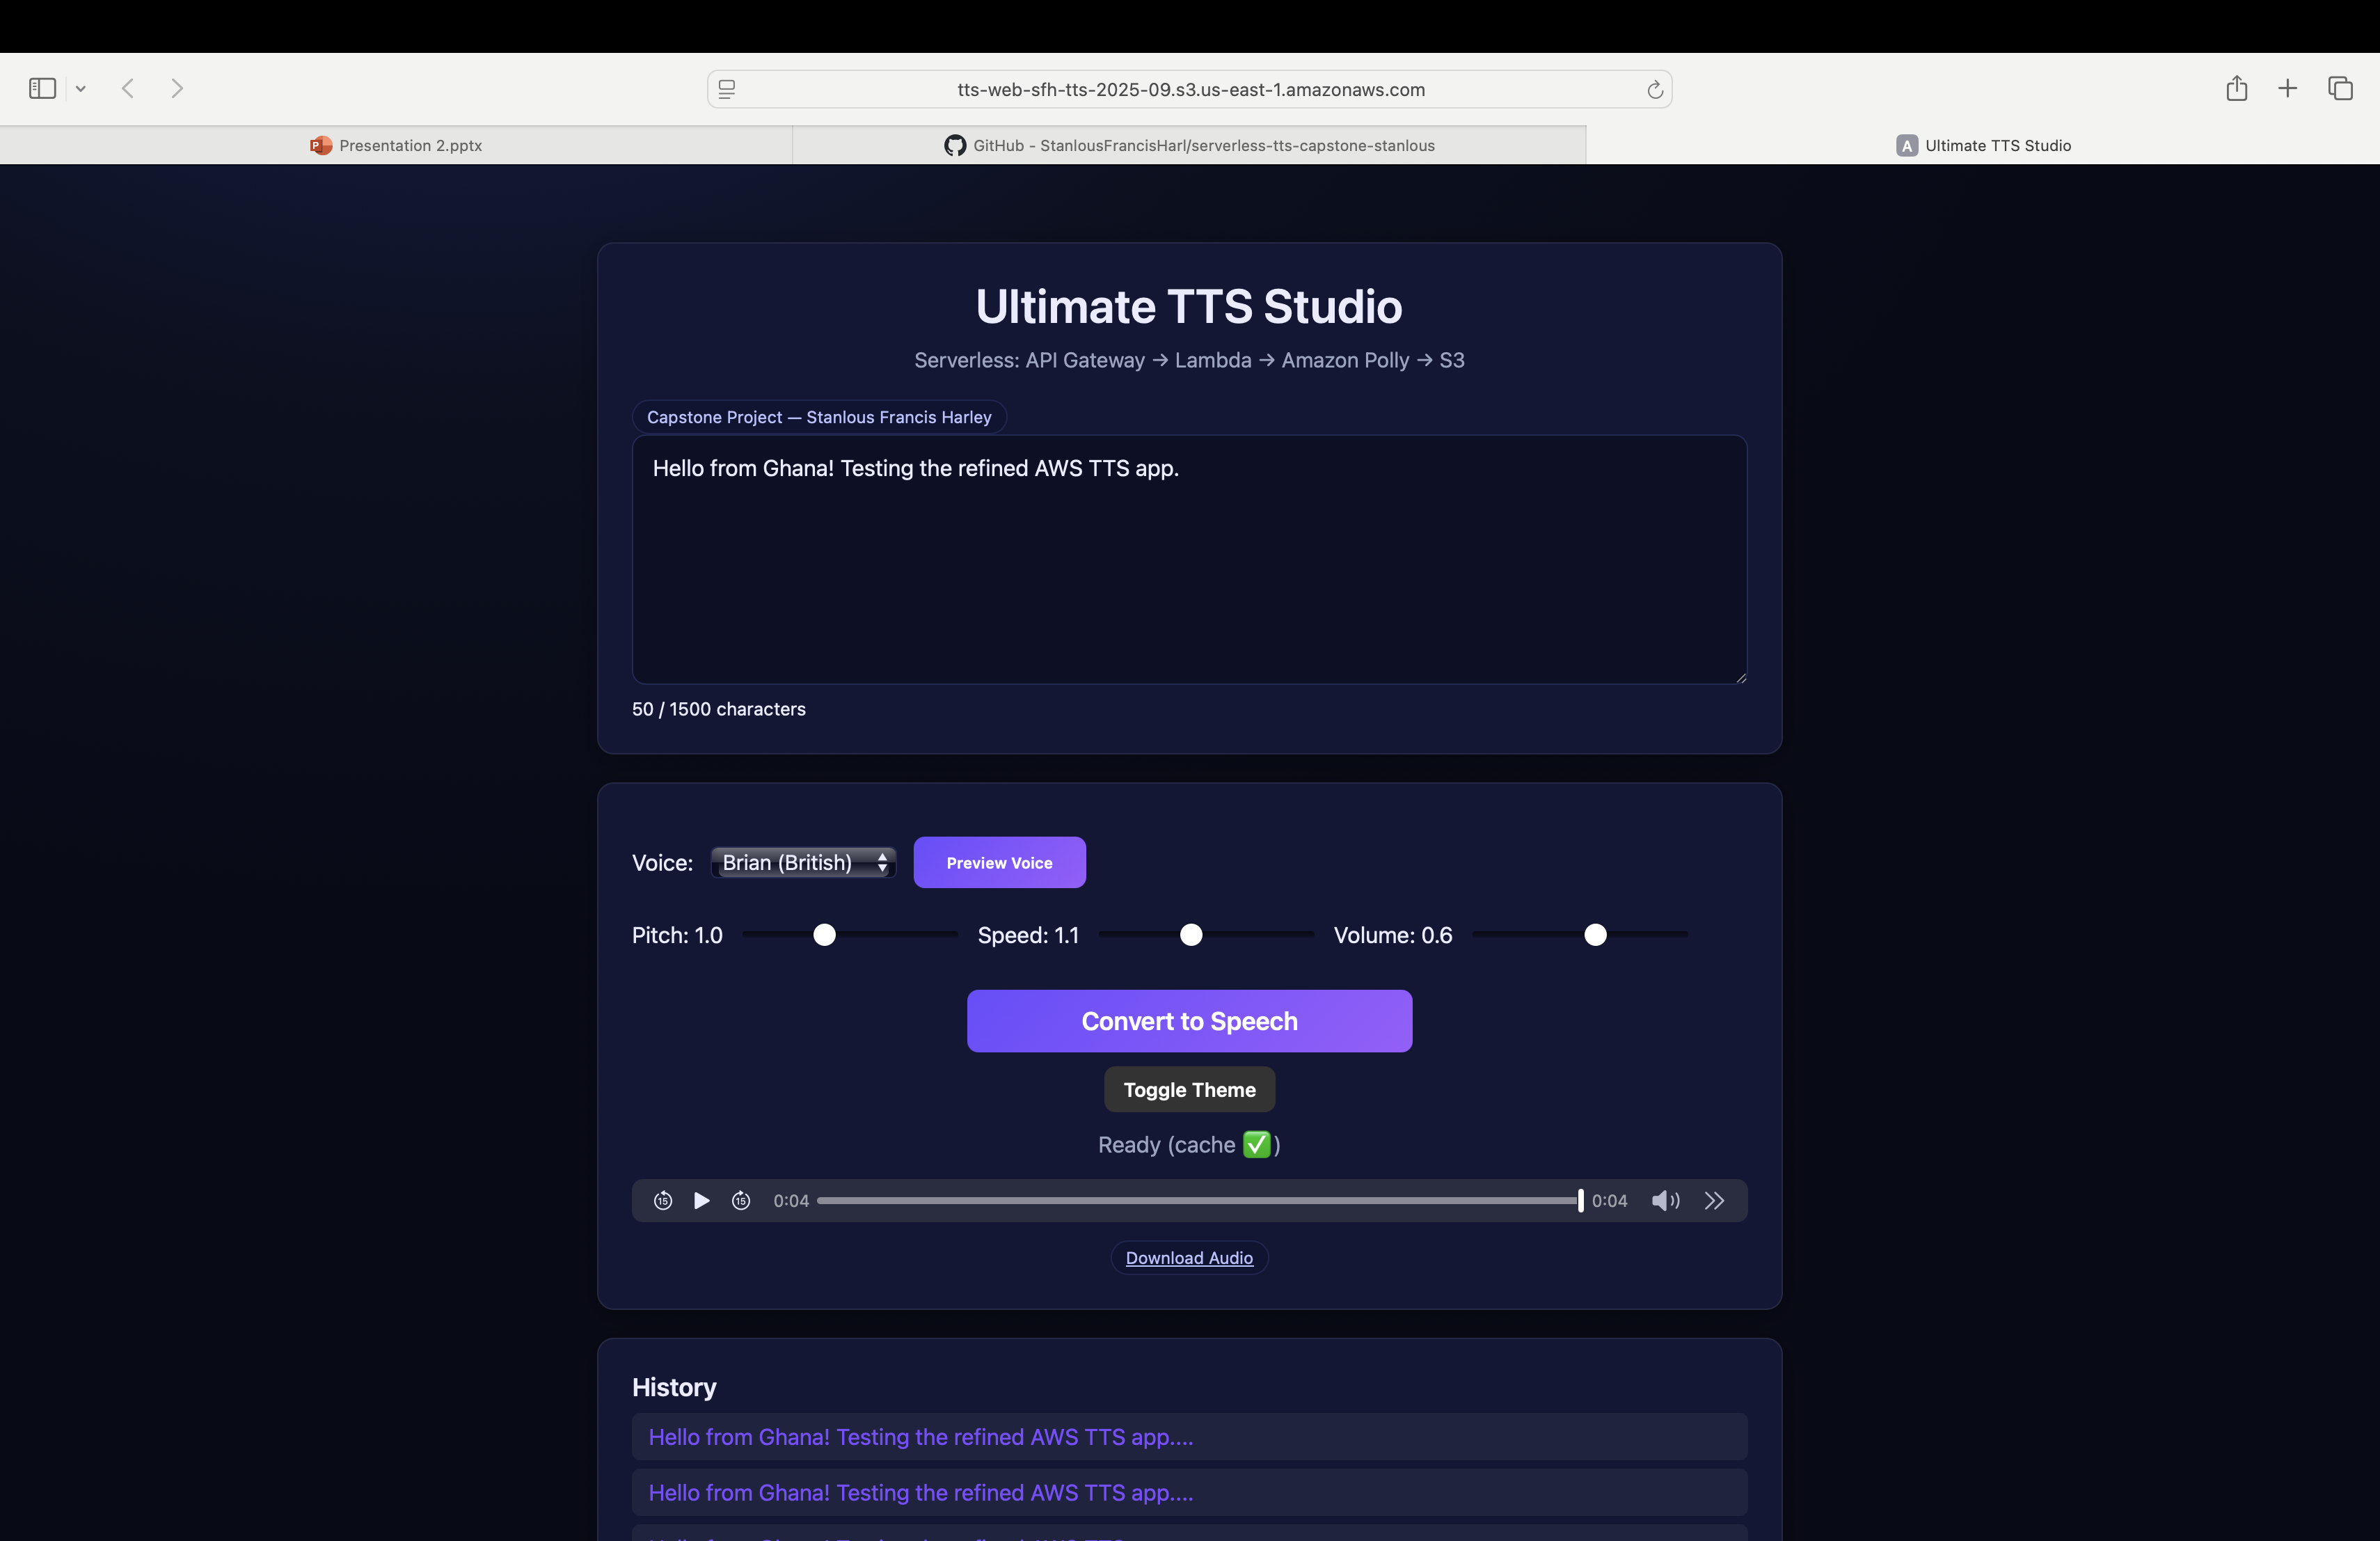
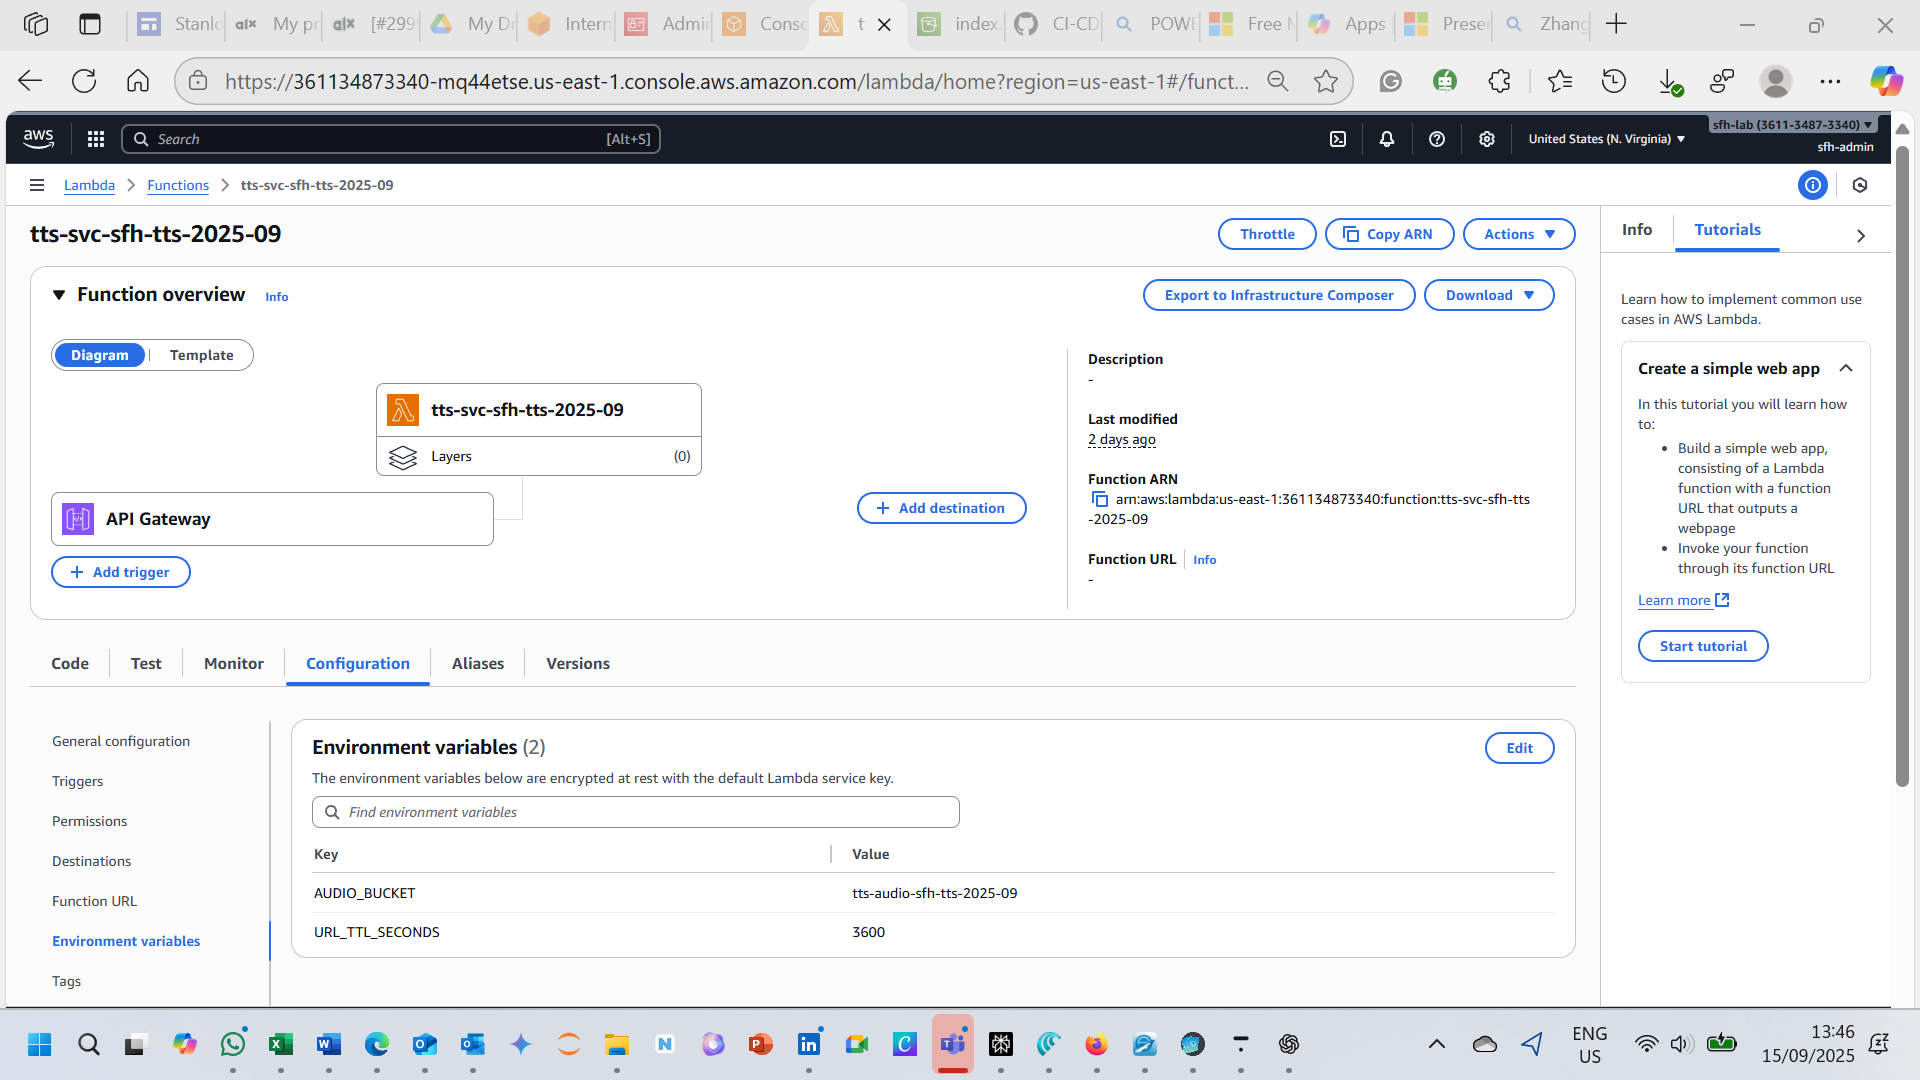
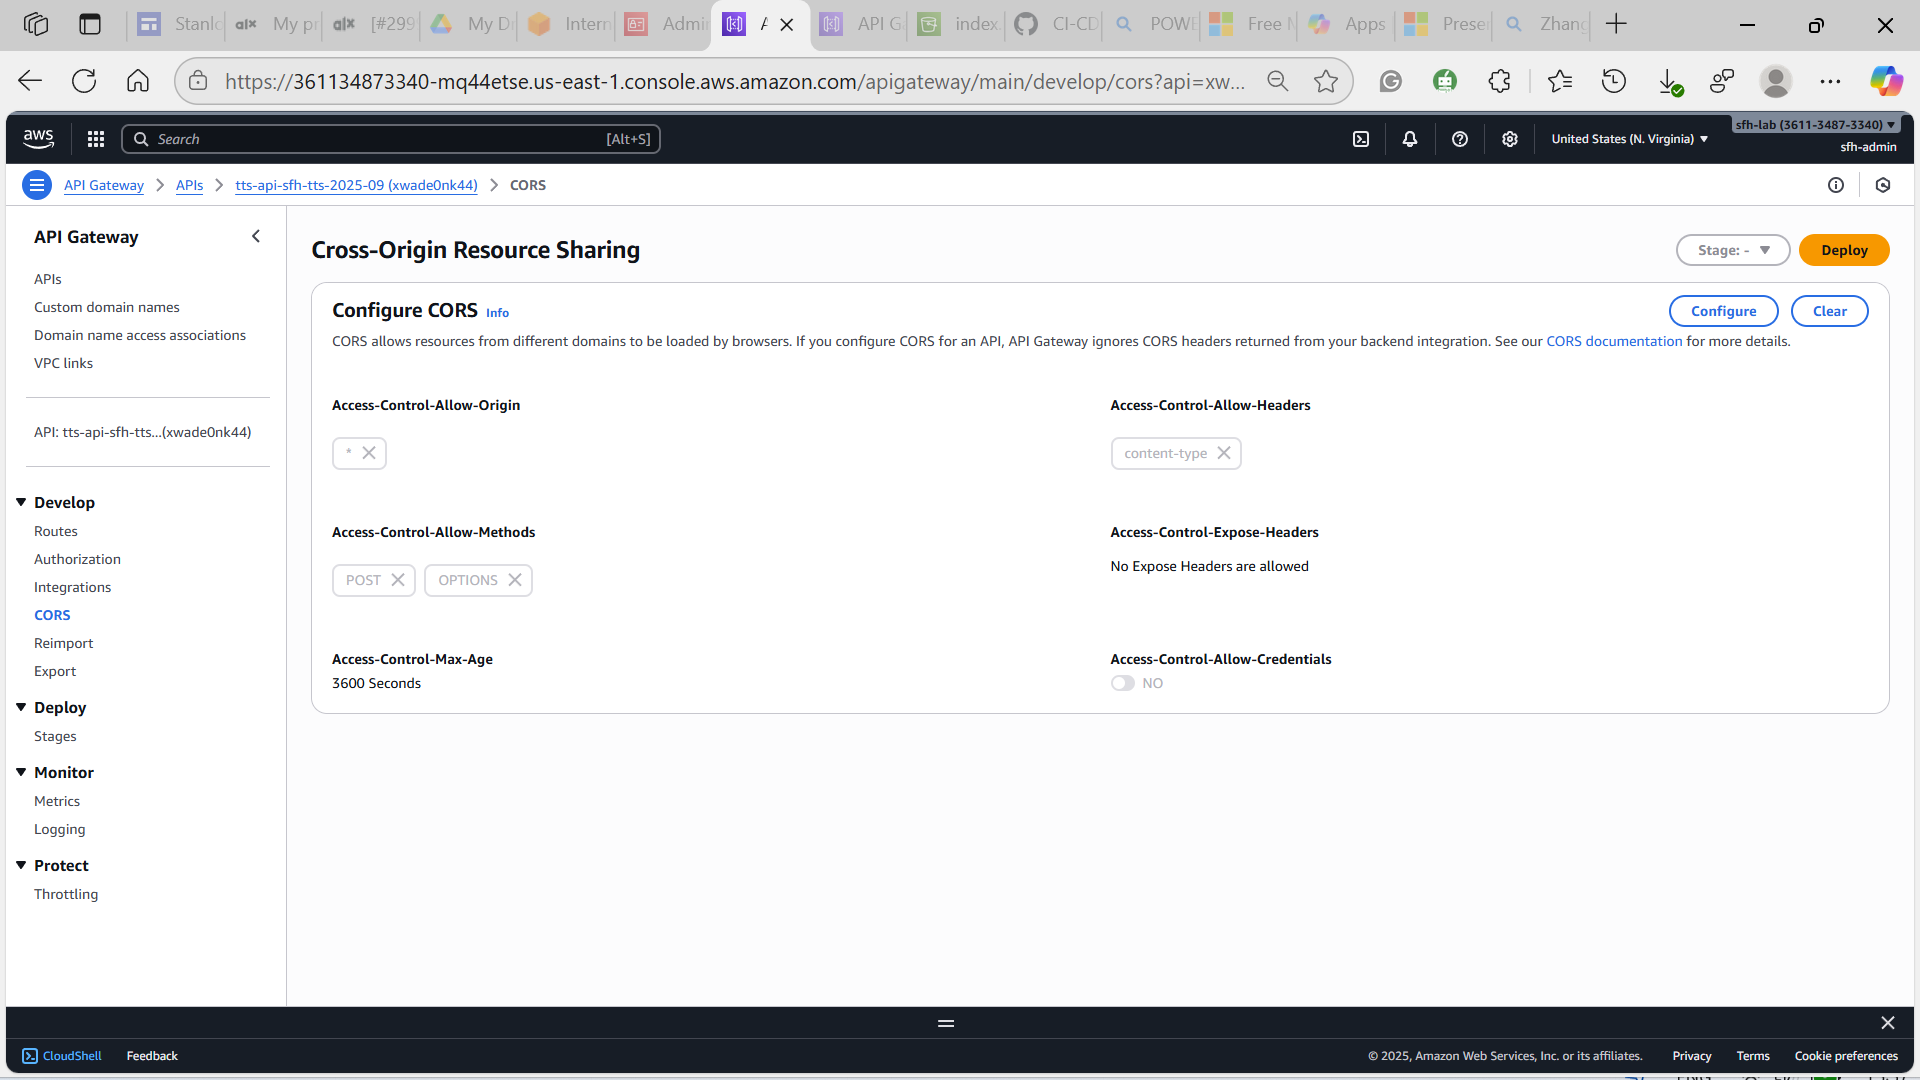
Implementation evidence
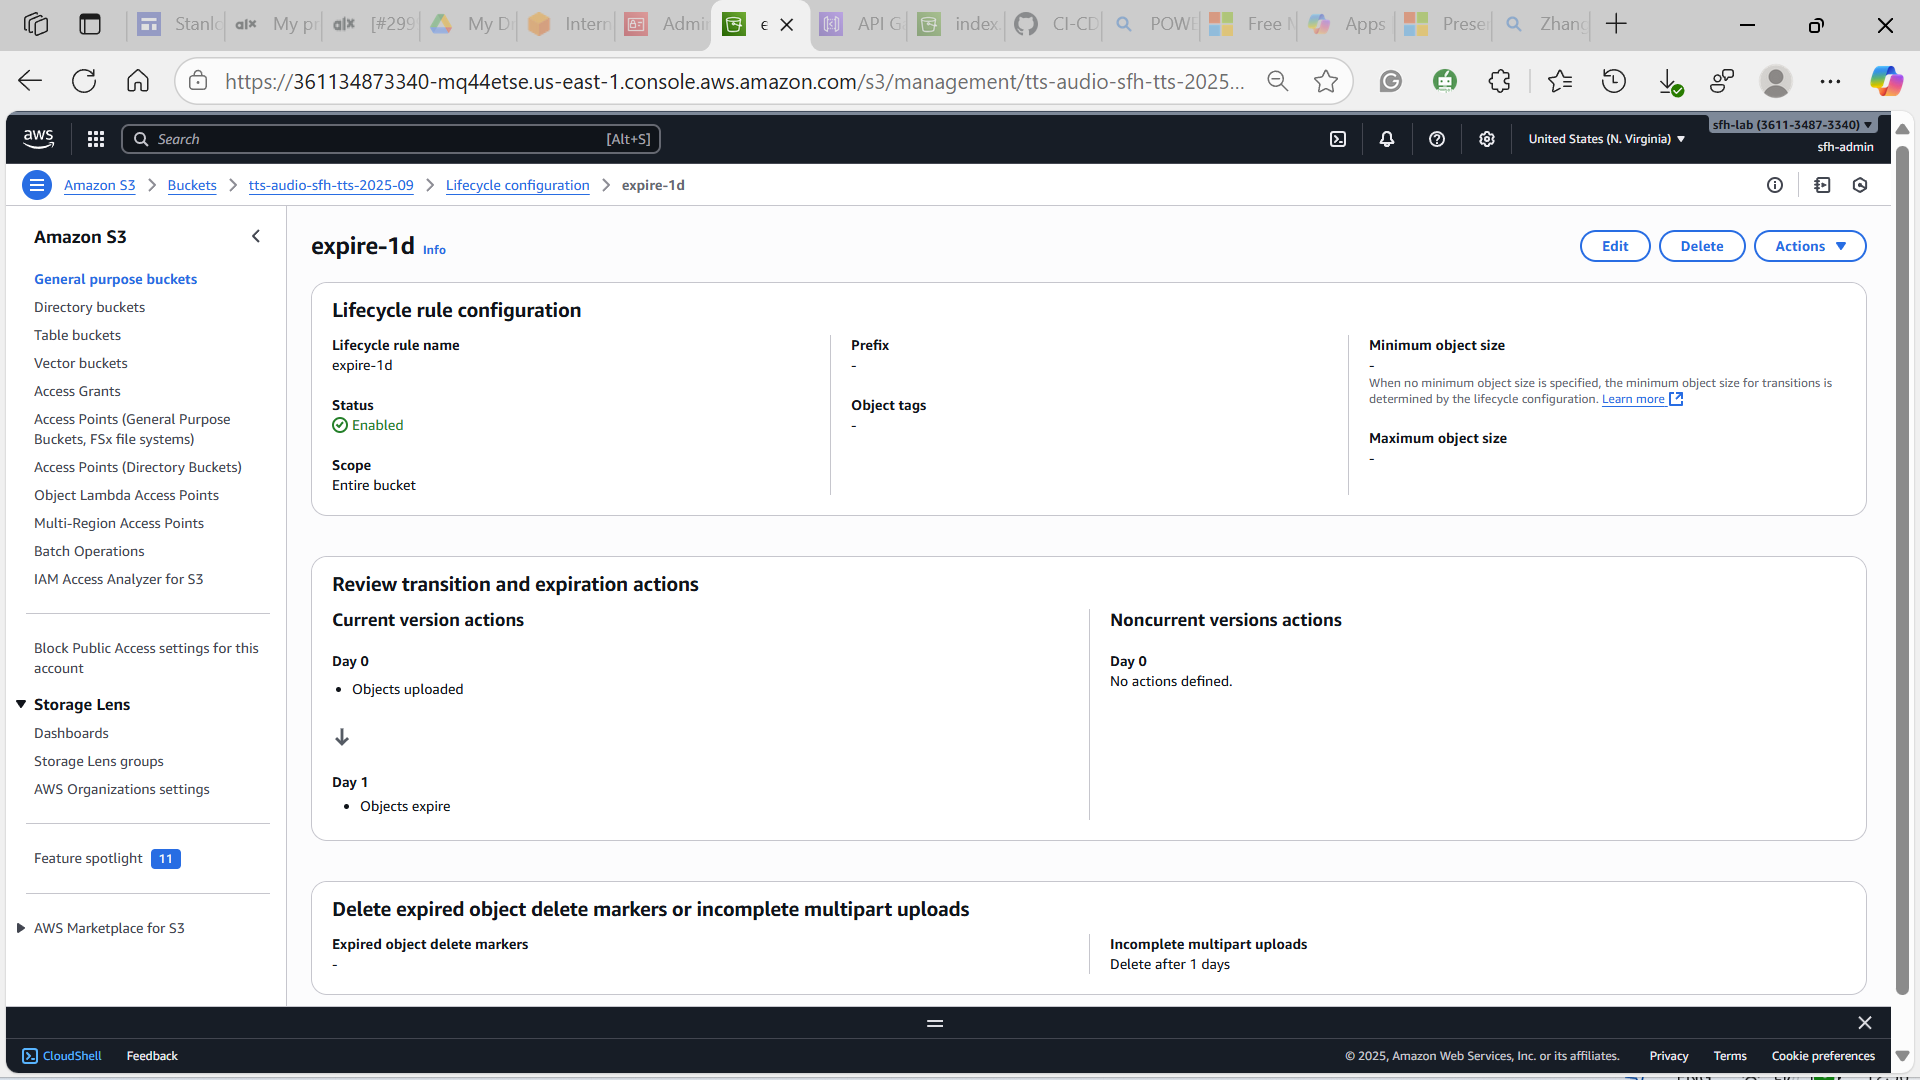
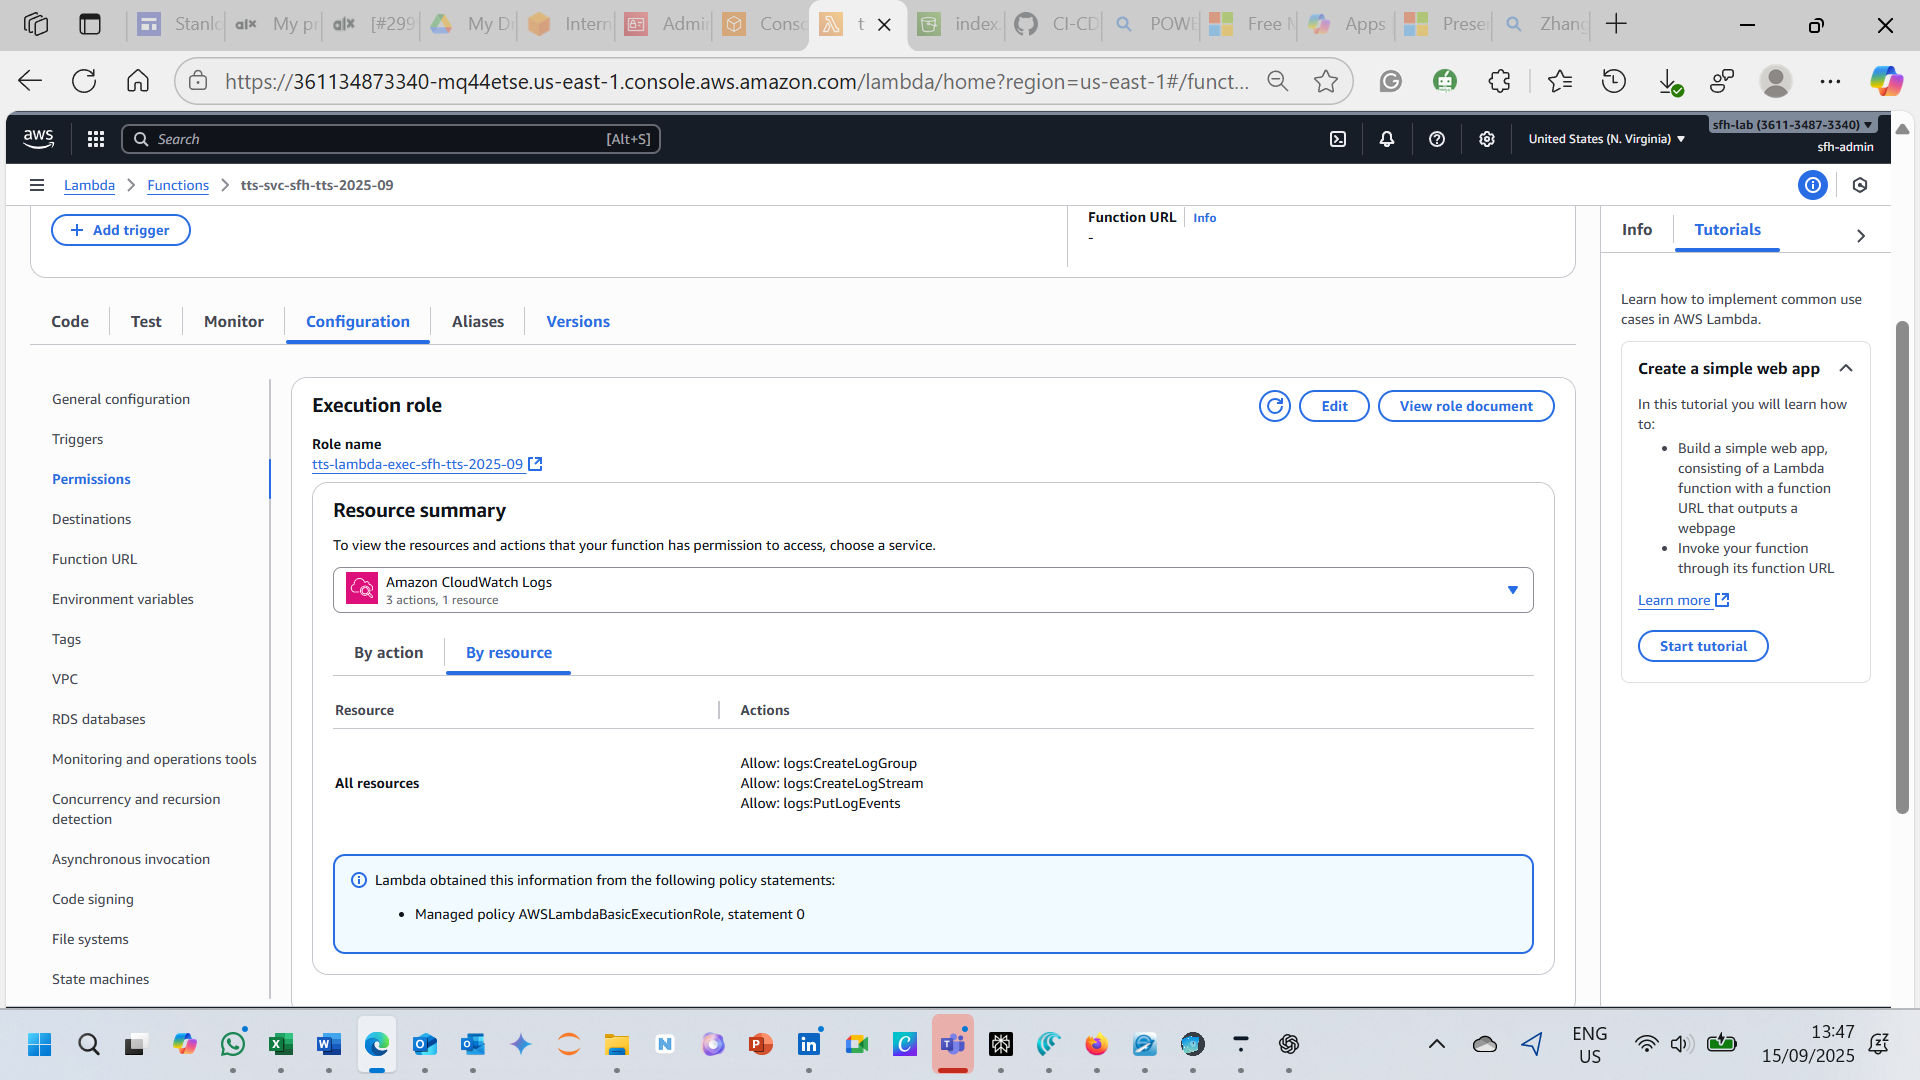
View the repository's actual implementation screenshots directly here.
Browse the source files
Read the public project documentation and implementation files directly on this page, without download links.
Public repository source · read-only preview
Loading project documentation…
Technology and resource structure
Frontend: static HTML hosted through Amazon S3. API: API Gateway HTTP endpoint. Processing: AWS Lambda (Python 3.12) invoking Amazon Polly. Audio delivery: private S3 bucket with short-lived pre-signed playback links and a one-day audio expiration policy.
Repository resources: README, CloudFormation template, Lambda function, frontend source, architecture diagram and documented evidence. Selected proof is displayed above without offering file downloads.